How Nodalview chose what to move: GPU inference on Runpod, everything else on AWS
Nodalview's engineering team on splitting a live production stack, handling a daily traffic spike and picking the right GPU for each job.
Most teams don't need to move their whole stack to get better GPU economics. They need to decide which part to move.
Nodalview, the AI photo and media platform for real estate agents, faced that decision with a live production stack on AWS. Their answer was narrow: move GPU inference to Runpod Serverless, and keep the web platform, storage, authentication and Kubernetes cluster where they were. That split has held as the pipeline grew to almost 1.5 million photos a month, with per-image turnaround under a minute once workers are running.
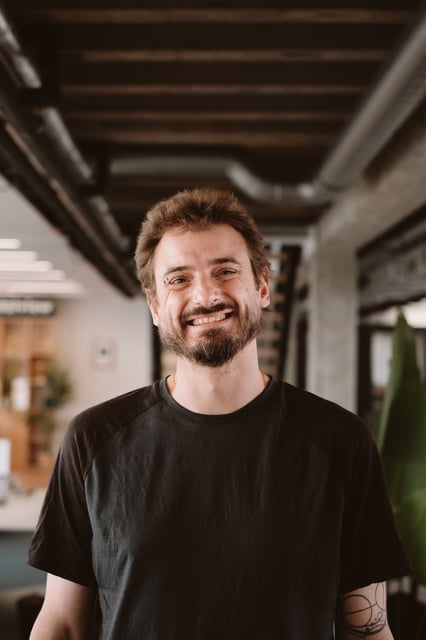
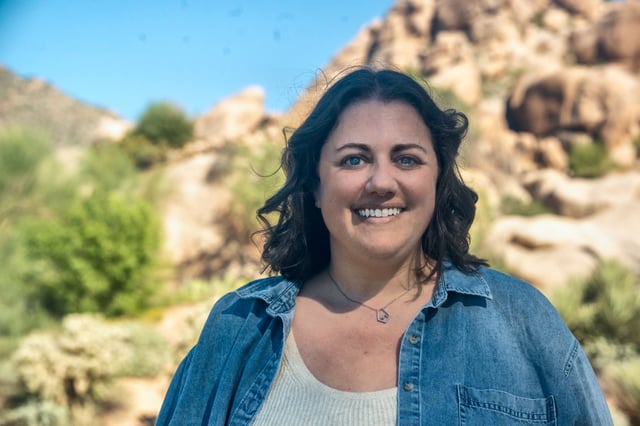
In this 30-minute session, Philippe Van Eerdenbrugghe, CTO at Nodalview, joins Brooke Spath from Runpod to walk through the architecture and the decisions behind it.
30 minutes · Demo + Q&A
Speakers
Philippe Van Eerdenbrugghe
CTO Nodalview
Brooke Spath
Head of Customer Marketing Runpod
You'll learn:
How Nodalview decided what to move and what to keep on AWS
How their pipeline handles a daily spike, with about half of the day's images arriving within two hours
Why cold starts mattered, and what they measured on a roughly 20GB model against AWS and Google Cloud
How they match GPUs to workloads across enhancement, virtual staging and room touch-ups
Who should attend: engineering leaders, ML engineers and platform teams running GPU inference in production, or planning to.
Hear what Nodalview would tell another engineering team weighing the same move.